The Voynich Manuscript (cryptography)
The Voynich manuscript is a fifteenth-century book in an unknown script that no one has read. Setting aside what it might say, the statistics of its text constrain how it was written.
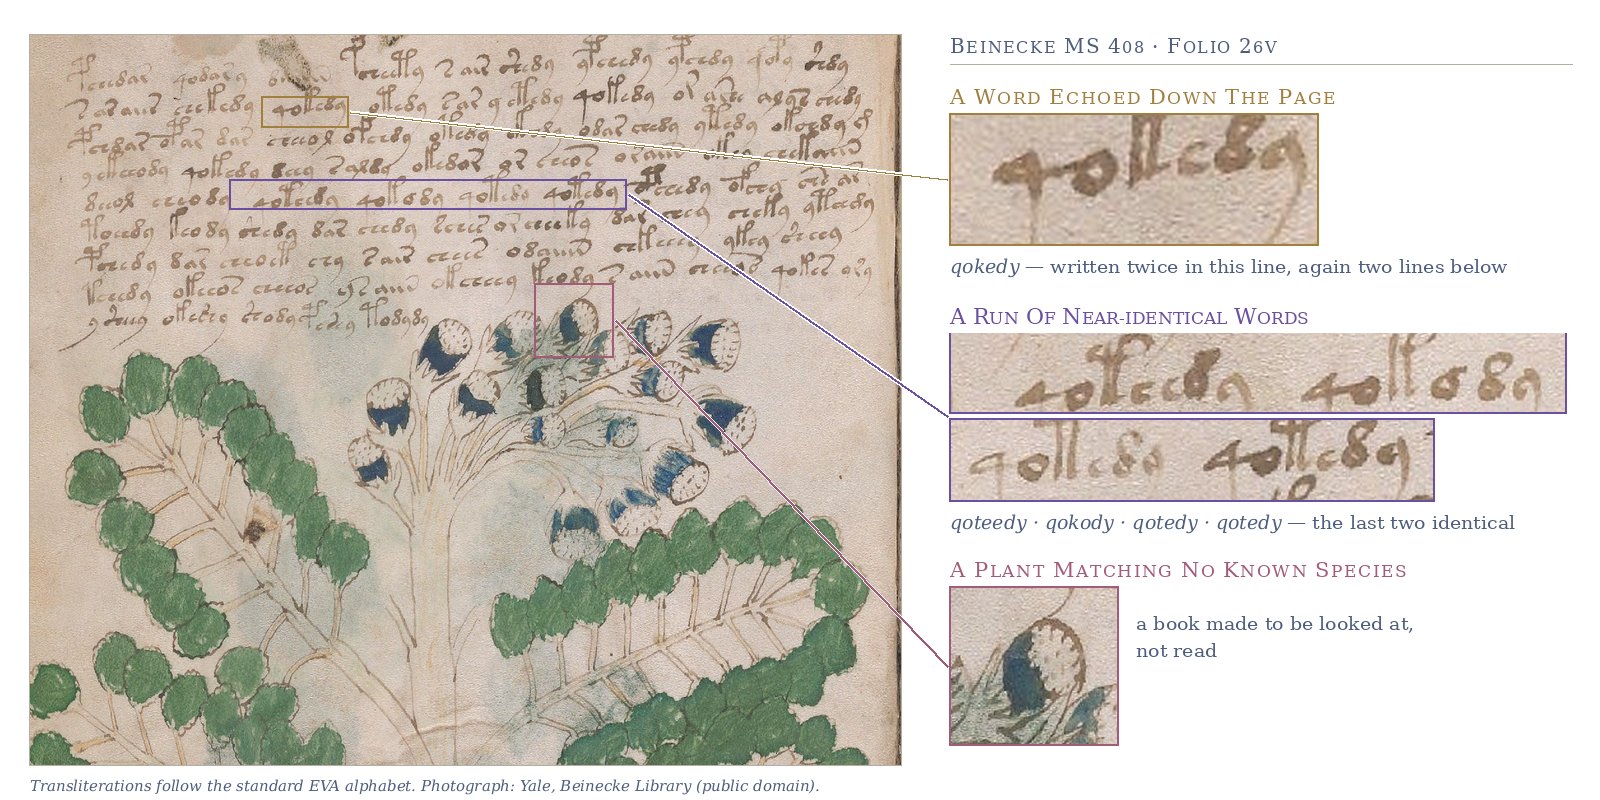
Folio 26v of the manuscript, a page from the herbal section, with three details magnified: a word written twice in one line and again two lines below, a run of near-identical words differing by a stroke or two, and one of the book’s plants, most of which match no known species. The same page, in transliteration, appears in the last figure below beside a page written by the recovered procedure. (Site illustration; image Yale University, Beinecke Library, public domain.)
A book no one can read
The Voynich manuscript, MS 408 of Yale's Beinecke Library, is a small book of about 240 pages of vellumParchment prepared from animal skin, the usual writing surface of a fine medieval book., radiocarbon-dated to between 1404 and 1438, with script and drawings that flow around each other, evidently made as one project. Drawings of plants, most matching no known species, fill 129 of the 227 text pages. The rest show astronomical and zodiac diagrams, bathing figures in green pools, labeled jars and plant parts, star-marked paragraphs usually read as recipes, and a few pages of text alone. The script occurs in no other surviving document. Its basic alphabet has roughly two dozen glyphA single written symbol of the script, named by its shape with no claim about what letter or sound it stands for. shapes, though inventories of over forty have been defended, so every count is taken under two different divisions of the script into characters. The writing is fluent, with very few corrections, so the scribes were doing something familiar.
The book's documented history begins only in the early 1600s at the Prague court of Rudolf II. An unverified secondhand report has Rudolf paying 600 ducats for it as a work of Roger Bacon. The book reached the Jesuit scholar Athanasius Kircher in Rome in the 1660s, stayed with the Jesuits until Wilfrid Voynich bought it in 1912, and has been at Yale since 1969. The ink and pigments indicate that the writing is as old as the vellum, which excludes Bacon, who lived in the thirteenth century, and a forgery by John Dee or Edward Kelley in the sixteenth.
Four centuries of readers
In 1921 William Romaine Newbold announced that the manuscript was Bacon's notebook, written in a microscopic shorthand hidden in the ink strokes. John Manly dismantled the reading in 1931: the shorthand was cracks in the drying ink, and the anagramming was so free that Manly produced counter-readings of his own. William Friedman and John Tiltman, among the best cryptanalysts of the twentieth century, both worked on it. Friedman concluded, in a 1959 footnote written as an anagram, that it was an early constructed language and not a cipher, and Tiltman endorsed no solution at all.
While attempts at decipherment failed, statistical facts about the text accumulated: the characters are more predictable than in any European language tried, and words have a rigid structure of prefix, core and suffix. Prescott Currier showed in the 1970s that the pages divide into two statistical "dialects," A and B, which change with the handwriting. Lisa Fagin Davis has since distinguished five scribal handsA hand is one scribe’s handwriting as a paleographer identifies it; pages in the same hand are taken to be one person’s work., an attribution adopted here without testing; Torsten Timm disputes it and argues for a single scribe whose hand drifted. The unusual statistics notwithstanding, a 2021 review by Claire Bowern and Luke Lindemann judged the text most likely a natural language in some non-standard encoding.
A second camp holds that there is nothing to read. In 2004 Gordon Rugg showed that a Cardan grille, a card with cut windows slid over a table of word fragments, mass-produces Voynich-like text, though the grille is a sixteenth-century device. Timm's 2014 study How the Voynich Manuscript was created proposed a copy-and-modify process. He and Andreas Schinner formalized it in 2020 as a “self-citation” generator, which reproduces several of the text's statistics. Cipher proposals kept arriving regardless, most recently the Naibbe cipher of 2025, a scheme executable by hand that turns Latin into Voynich-like text. A cipher still has defenders, and Bowern and Lindemann argue for a language, but much of the recent quantitative work has come to favor a writing procedure that carries no message. The tests described below aim to make that picture precise.
Weighing one explanation against another
Announced readings have generally come from searching many keys, languages and rearrangements for language-like output, which Manly showed can be found in almost any text given enough freedom. The self-citation generator, for its part, had never been tested on text withheld from its fitting, so far as the author knows. Here both are put to the same test: each reading and each generator becomes a probability model for the glyphs on a page, fitted on half of a scribe's pages and judged on the half withheld from the fit. Most tests run on the pages of the two principal hands, Scribe 1, who writes dialect A, and Scribe 2, who writes dialect B. Models are compared by their evidence, the probability each assigns to the text once its adjustable parameters are averaged out:
$$Z_M \;=\; P(\text{text} \mid M) \;=\; \int P(\text{text}\mid\theta, M)\, P(\theta \mid M)\, d\theta .$$Here $M$ is a model, say "Latin under a substitution cipher with an unknown key," $\theta$ collects its unknown parameters, $P(\text{text}\mid\theta, M)$ is the probability of the text at one setting of them, and $P(\theta \mid M)$ is their priorThe range of parameter values treated as plausible before seeing the text; averaging over it charges a model for flexibility it does not need. spread. The average runs over every setting instead of the best one. A model flexible enough to produce almost any text therefore earns little credit for fitting this one; a free search pays no such penalty. For the count-based models used here the integral is exact. The reading tests score a decode of the withheld pages against a language's word and letter statistics, and the writing procedures are compared by the bits a fitted generator needs to predict each withheld word. Most comparisons below are quoted in bits per word, and one bit per word doubles the odds with every word read.
Every solver, the search program that fits a reading's key or table, first had to recover a known answer from real Latin, Hebrew or Arabic disguised by the mechanism under test. Three such checks fell short, and the results they affect carry that caveat. The reading tests are calibrated on scripture in six languages, Latin, Hebrew, Arabic, Italian, German and English, cut to the manuscript's page layout. The production comparisons use a Latin herbalA book describing plants and their medicinal uses, one of the commonest kinds of medieval technical writing., biblical Hebrew, medical Arabic and Dante, with 23 further texts, recipes, glossaries and a botanical catalog among them, added for word order. The manuscript itself enters the analysis as a standard transliterationThe Zandbergen–Landini transcription of the script into the Extensible Voynich Alphabet (EVA), whose Latin letters name glyph shapes without any claim about their sound; maintained by volunteer scholars. Everything is counted under two different divisions of the script into characters. of its 227 text pages, about 38,000 words.
The readings fail, and what that excludes
A century of proposed readings falls into five families: substitution, one glyph per letter; verbose substitution, a group of glyphs per letter; consonantal writing with the vowels left out; Latin abbreviation; and codebooks, each word a token in a private table. Composites and the Naibbe cipher, built from its published tables, are added. Counted across languages, hands and character divisions, that makes 130 hypotheses, each judged by whether its decode of the withheld pages has the letter and word statistics of the language claimed. In further runs, judged against control texts, the solver also searches ten alternative reading ordersThe order in which glyphs are taken off the page before any decoding: right to left, by columns, alternate lines reversed, or interleaved., and divisions of the script into characters of its own choosing, together with the mapping. Free anagramming, on which Newbold's reading relied, is left out on purpose: at this text length it admits almost any answer, so no test could contradict it. Anagramming by a fixed rule within each word, the last stage of a 2016 Hebrew proposal by Bradley Hauer and Grzegorz Kondrak, is testable and is tested.
None of the 130 hypotheses passes on the withheld pages. The nearest simple substitution, into Hebrew, falls 2.8 bits per word short of the passing mark, a word-level score calibrated on scripture in each language; the nearest verbose reading falls 1.1 short, the nearest consonantal one 2.1, the Naibbe mapping 1.5 and Latin abbreviation 5.7. The ordinary reading order fits better than any of the ten alternatives, and re-dividing the script into characters brings the text no closer to any language.
What a failure proves depends on whether the test would pass a true reading of the same kind. This selectivity was measured on 22 real texts in the six languages (scripture, herbal, medical, technical and narrative prose, recipes), disguised by up to sixteen encodings at four levels of transcription noiseRandom single-character errors of the kind a copyist or transcriber makes, simulated at a fixed rate per character.. The test reliably accepts a correct reading only of scripture-like prose at low noise, and there only for substitution, fixed-rule anagramming, abbreviation and narrow homophonic ciphers (each letter written by any of a few alternative signs), in some languages. Because its passing mark was set on scripture, it accepts a correct reading of the other genres in about one trial in a hundred at best, while a matched control text containing no reading passed in none of 7,030 trials. The exclusions therefore hold for scripture-like text and carry no weight for herbal, medical, recipe or narrative text in any language. Two further limits lie in the search itself: full-width verbose tables were searched for Latin alone, and on the Naibbe class of cipher the solver recovered nothing in 1,370 trials on texts enciphered with freshly randomized tables of the same design, so nothing can be claimed about that class either way. Fixed-rule anagramming into Latin, Italian, German or English is rejected on both hands by 2.2 to 5.0 bits per word; for Hebrew and Arabic the test is uninformative, since it also accepts an Arabic reading of disguised German and English texts.
A further experiment suggests why readings keep being announced. Modern decipherment attempts search many mappings for the one whose output looks most like language, and such optimizers, run unconstrained on the manuscript, "succeed" every time. But the decoded "Hebrew" and "Arabic" use eight to ten of some twenty letters, and the same pages decode equally well into both languages, which no genuine reading permits. The remedy is to require the output to be language-shaped, with a real language's letter and vocabulary statistics, and to compare the manuscript with a meaningless self-copying text searched with the same freedom. The manuscript's advantage over that control then collapses, from 4.1 to 0.26 bits per word in the Hebrew test, run on Scribe 1's pages, and from 6.3 to 2.6 in the Arabic test on Scribe 2's. The remaining Arabic advantage is carried by a decode that fails the shape requirement on the withheld half. Three to four bits per word of apparent signal thus seem to come solely from the search's reward for language-like output, perhaps enough to account for much of the history of announced readings.
How the pages were written
With no reading passing its test, the question becomes how the text was made, studied here on the pages of the two principal hands that are unmixed in dialect. The candidate processes, among them a habit chain in which each word depends on the one before, Rugg's grille, and Timm and Schinner's copying from nearby lines, each became a working generator. They are compared against a reference with no procedure at all, a memorized vocabulary drawn on regardless of order (a "bag of words"). Two statistics, both built from cross-entropies (the average bits a fitted model needs per word of the withheld half), then separate the manuscript from each of the four comparison languages on which these models were run:
$$G_{\mathrm{order}} \;=\; H_{\mathrm{vocab}} - H_{\mathrm{chain}}, \qquad H_M \;=\; -\frac{1}{N}\,\log_2 P_M(w_1 w_2 \cdots w_N \mid \text{layout}) .$$Here $w_1 \cdots w_N$ are the $N$ withheld words with their line layout given, $P_M$ is the probability that model $M$ assigns them, and "vocab" and "chain" are the bag of words and the habit chain. So $G_{\mathrm{order}}$ is the predictive gain from knowing the previous word. For Latin, Hebrew, Arabic and Italian laid into the manuscript's page templates it is 0.15 to 1.06 bits per word; on the two hands it is 0.010 to 0.022. The companion gain of a memorized word list over spelling habits is 1.3 to 3.0 bits in the four languages and at most 0.18 here. Twenty-three further texts were laid into the same templates, among them technical and medical Latin, recipe collections, glossaries, an index and a botanical catalog. Every one shows more word order than either hand under any model class fitted; the nearest, a list-like stretch of Pliny on trees, reaches 0.039, and the botanical catalog shows the most of all. Adjacent words do share something at their edges: the last glyph unit of one word predicts the first unit of the next by about 0.12 and 0.21 bits on the two hands, against at most 0.11 in the four comparison languages. Only some recipe collections and the catalog show as much of this edge coupling or more.
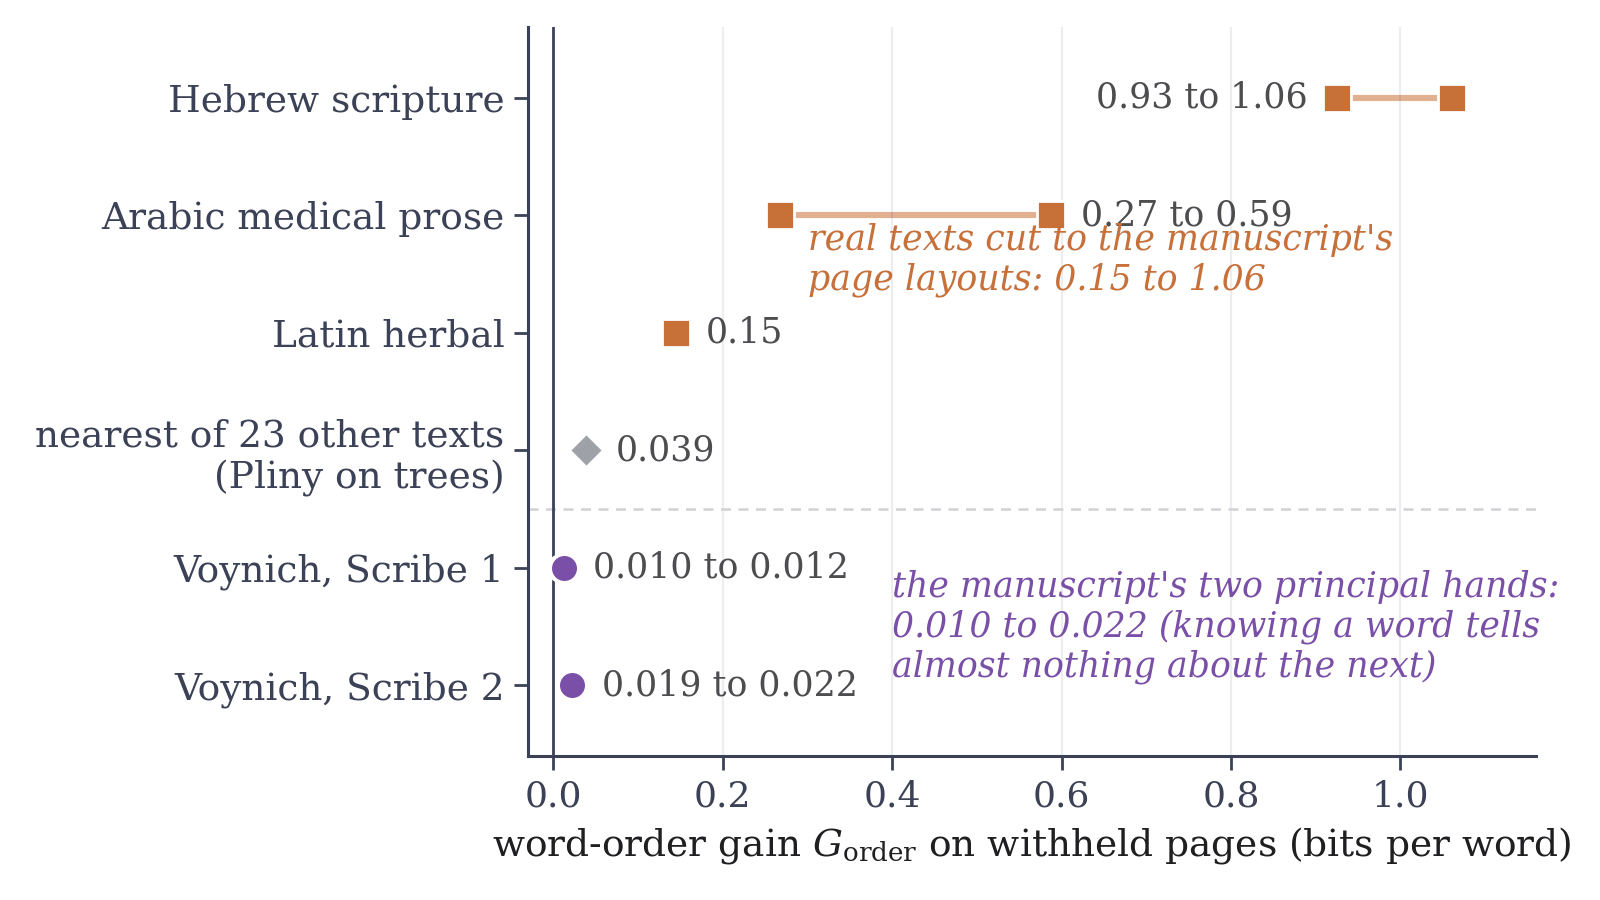
How much knowing one word helps predict the next: the word-order gain of the equation above, measured on withheld pages in bits per word. Orange squares are real texts cut to the manuscript’s page layouts, Hebrew scripture, Arabic medical prose and a Latin herbal; where a text was cut to both scribes’ layouts its two values are joined (Italian, not plotted, falls inside the same 0.15 to 1.06 range). The gray diamond is the nearest of the 23 further texts, a list-like stretch of Pliny’s Natural History on trees, at 0.039. Violet circles are the manuscript’s two principal hands, each under both divisions of the script into characters, at 0.010 to 0.022. In the manuscript the previous word tells almost nothing about the next, less than in any text compared. (Redrawn from Figure 5a and Table 2 of the paper.)
By exact evidence, whether the bag of words or the habit chain ranks first depends on the prior placed on the chain, and where the chain wins, its margin is a few hundredths of a bit per word. The grille, as parametrized, fits worse than the bag on both hands, and copying from nearby lines is a real component, decisively better than its shuffled control. Scored the same way, genuine output of Timm and Schinner's generator behaves differently: local copying fits it better than the bag of words does, and its copy rate is above either hand's, so self-citation in its published, local form does not appear to be the manuscript's process. Copying from much further back, though, is statistically the same as reusing a growing personal stock, so Timm's broader account, one writer citing his own drifting text, is not excluded by any statistic of this kind.
The process that fits the text is a loop of two or three small decisions per word. Most words are reused, drawn by frequency from the scribe's own stock: 72.9 percent of Scribe 1's withheld text and 76.7 percent of Scribe 2's. A few are copied from one of the last twenty or so words, about one in fifty (2.0 percent) for Scribe 1 and one in twenty (4.9 percent) for Scribe 2, whose copies are nearly all verbatim. Scribe 1's fitted copying cannot be separated from what page-to-page variation in word frequencies alone would produce, whereas Scribe 2's can. The rest, a quarter of Scribe 1's words and under a fifth of Scribe 2's, are coined afresh in the scribe's letter habits, so closely that a letter model predicts them as well as the vocabulary does.
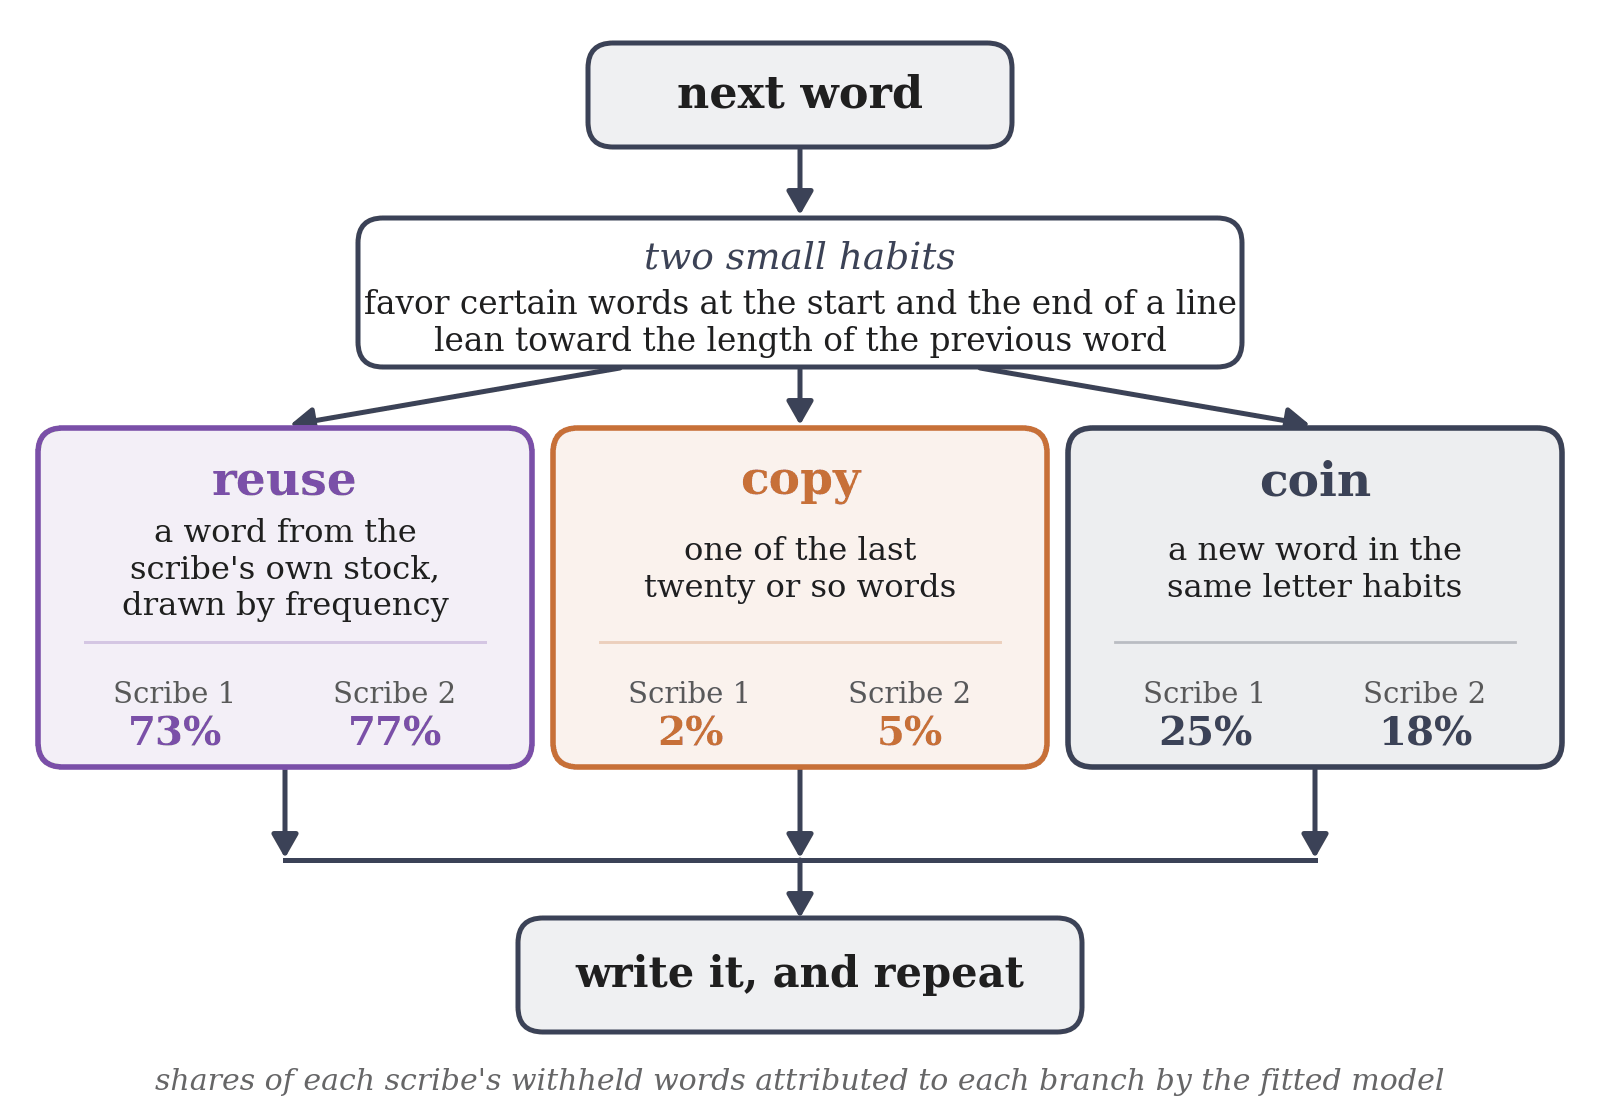
The recovered writing procedure. Each word is one pass through the loop: two small habits of line position and word length, then one of three choices. The percentages are the shares of each scribe’s withheld words that the fitted model attributes to each choice: reuse of a word from the scribe’s own stock (73 and 77 percent), a copy of a recent word (2 and 5 percent), or a fresh coinage in the same letter habits (25 and 18 percent). No step involves a key or a source text, so text written this way leaves no message to decipher. (Redrawn from Figure 6 of the paper.)
Two smaller habits complete the procedure: a preference for particular words at the start and end of a line, and a tendency for each word's length to follow the previous word's. With these added, the complete model beats reuse, copying and coinage alone by 0.14 to 0.19 bits per word on fresh page splits. Pages it writes fall outside the manuscript's own page-to-page range on two of 22 summary statisticsSingle numbers describing a page of text, such as how often words repeat, the mean word length, or how fast new words appear. for the first hand and three for the second; pages simulated from the fitted model itself miss at least that many with probability 0.16 and 0.06, so these counts do not by themselves reject the model. Simple controls miss six to eleven of the 22, Timm and Schinner's output seven and five, and Naibbe ciphertext nine and thirteen. The model still misses a few statistics outside those 22, above all the edge coupling between adjacent words, which no generator yet proposed reproduces either.
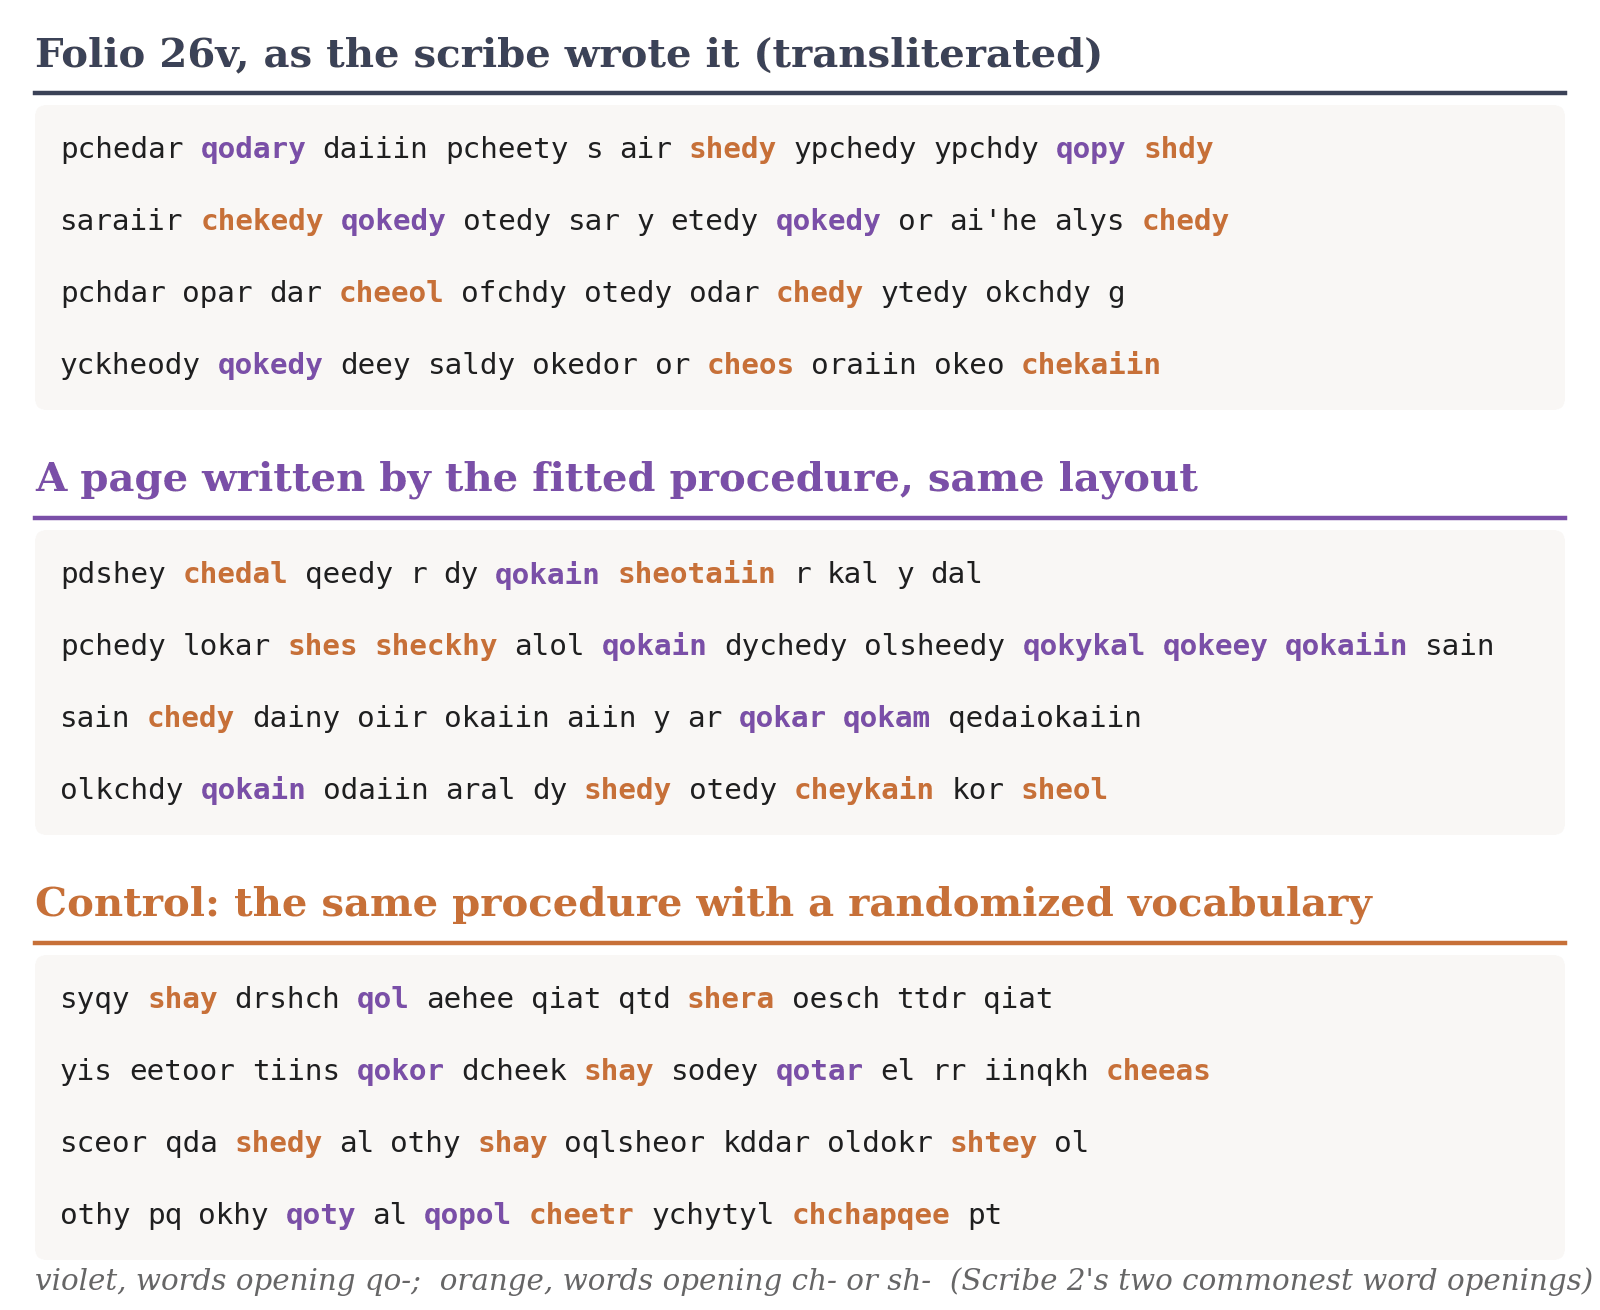
Real lines, generated lines and a control. Top: the first four lines of folio 26v in transliteration, a page in Scribe 2’s hand that the fitting never used. Middle: the first four lines of a page written in the same layout by the complete fitted procedure. Bottom: four lines from the same procedure with its vocabulary replaced by a random draw. Violet marks words opening qo- and orange ch- or sh-, Scribe 2’s two commonest word openings. The real page’s mix of word skeletons and its runs of near-identical words recur in the generated lines and vanish in the control. The comparison is an illustration; the quantitative test is the count of missed statistics above. (Re-set from Figure 10 of the paper, Appendix C.)
The two hands' vocabularies, of 3,155 and 2,389 distinct words, are built alike. Every word is split by one fixed rule into prefix, core and suffix: the first two glyph units, whatever lies between, and the last two. The two hands' prefix and suffix inventories largely coincide (an overlap indexThe Jaccard index: the number of items two inventories share divided by the number in either; 1 for identical inventories, 0 for nothing in common. of 0.65 for prefixes and 0.48 for suffixes) while their cores barely do (0.23). But two halves of either scribe's own pages split the same way (cores 0.23 to 0.28), as does every comparison language cut in two. Any productive spelling habit therefore yields this pattern, so it is no evidence that tables of word parts passed between the writers, or that such tables were ever written down. The cores look like coinages of each scribe's letter habit: families of one-glyph variants such as kcheo, kheo, pcheo, scheo, ssheo, lsheo, theo make up a little under 60 percent of each core vocabulary. An ordering statistic shows no sign that the cores were copied out from a written grid. Apart from a slight same-page excess for Scribe 1, the members of a family first appear no closer together in the text than unrelated cores do, so they do not seem to have been coined in one run.
Two faint traces of the pictures
Meaning could still lie in the labels or in the choice of words. The tests for it control for scribe and page order, and two weak traces survive those controls. The first trace is in the 864 labels beside the drawings, which form a registerA variety of a language tied to a particular use or setting, with its own habits of word choice. of their own. On the pharmacy page f88r the six top-band labels read otorchety, osal, orald, oldar, otoky, otaly, all opening with o-, and across the book three labels in five are o-initial, against one word in three in matched running text. Names, though, would recur with their objects, and the labels repeat across pages less often than chance: 75 types on more than one page against 85 to 111 expected. The test has limited sensitivity, so a sparser naming system could have escaped it, and a name used once for one star cannot be tested at all.
The second trace is a faint dependence of a page's vocabulary on its subject. The search covered seven channels, ranging from the words a page uses to the glyph units that fill each position in the word. Only the mix of word types on a page tracks the illustrated section beyond what scribe and page order explain, and it still does when tested against fake contiguous sections and against fake sections aligned to the quiresThe folded gatherings of sheets from which a codex is sewn together. In this book the sections, the hands and the quires are physically entangled, so a signal that follows the binding can masquerade as one that follows the subject.. The effect is about 0.2 to 0.3 bits per page, marginal under the harshest controls, and it comes from the astronomical and bathing sections; the herbal section, the largest, shows none. One survivor out of seven channels tried is weaker support than an independent confirmation. Beyond these two traces the tests find no dependence between words past the coupling of adjacent word edges, no stable names, and no mapping to any language or mechanism examined, each within the sensitivity of its test.
What kind of book, and what would change the answer
The reconstruction of how the pages were written is a proposal, the process most consistent with the measurements. It was fitted on two hands and extends to the others largely by inference; the vocabulary statistics cannot tell several writers trained in one spelling habit from one writer whose habit drifted. The routine takes practice, as the fluent penmanship suggests, but no literacy in any particular language, no knowledge of ciphers, and no apparatus such as Rugg's table and grille. Why the book was made can only be inferred. Assuming ordinary scribal rates, the text is 40 to 80 hours of writing, little beside preparing a hundred leaves of vellum and the drawings. The low cost of the writing and the secret-knowledge genres its sections imitate suggest a book made to be looked at and believed, as a practitioner's credential or for sale to a collector of marvels.
On the question of what the text says, the results are negative within a stated space of readings. Where the test demonstrably passes a true reading of the same kind, the scripture-like cases above, the manuscript's failures exclude those readings. The other readings in the space are constrained only by the requirement that any encoding yield characters as predictable as the manuscript's, and by the production evidence. Free anagramming cannot be tested at this length and lies outside the space altogether.
On the question of how the text was produced, the measurements sharpen a picture that has been emerging since the work of Rugg and of Timm and Schinner, though no generator so far, the one fitted here included, reproduces the edge coupling. The two traces of content suggest that the writers tracked the pictures; neither shows that the text describes them, and meaning carried by anything but word identity and order would be invisible to every test used. Several findings would overturn the reconstruction: a confirmed reading of any passage, provided it passed where past claims failed, on withheld text, against matched controls, and for one specific language; a passage that predicted the imagery in detail; a natural language that matched the manuscript on the word-order and vocabulary comparisons; or evidence from the physical book, beyond the published study of its quires and binding, that the text was not written onto finished drawings.
The paper
- How the Voynich Manuscript was written (PDF) — Matthew D. Schwartz. A preliminary version of the paper.
Supplementary material
The transliteration of the manuscript is public; the script below verifies a downloaded copy against a recorded fingerprint before it computes anything.
- voynich.nu — the public source of the Zandbergen–Landini transliteration (file ZL3b-n.txt), the form in which the manuscript enters the analysis. To run the script below, download ZL3b-n.txt from voynich.nu and place it in the same folder as the script, which reads the file from there unless given another location with --data FILE.
- voynich-evaluate.py — a small verification script, Python standard library only, that recomputes two of the paper’s numbers from that transliteration file, the dialect of each of the 227 text pages by exact evidence and the labels’ o-initial rate against its matched expectation, and exits nonzero if either disagrees with the recorded value.
- Mixalot — the tool page on this site for the exact mixture-evidence software used in that page-by-page dialect classification.
- Exact Bayesian evidence for mixture models (PDF) — the related paper, by Matthew D. Schwartz and Subhabrata Sen, which derives the exact evidence formulas that software evaluates.
References
| W. R. Newbold, The Cipher of Roger Bacon, University of Pennsylvania Press, Philadelphia (1928) | announced the book as Bacon’s notebook in a microscopic shorthand hidden in the ink |
| J. M. Manly, Roger Bacon and the Voynich MS, Speculum 6 (1931) 345 | dismantled that reading: the shorthand was cracks in the ink, the anagramming unconstrained |
| W. F. Friedman, Anagrammed conclusion on the Voynich manuscript, footnote in Philological Quarterly (1959) | his verdict, deposited as an anagram: an early constructed language, not a cipher |
| J. H. Tiltman, The Voynich manuscript: “The most mysterious manuscript in the world”, address to the Baltimore Bibliophiles (1967) | cataloged the rigid structure of the words and endorsed no solution |
| P. H. Currier, Papers on the Voynich manuscript, in New Research on the Voynich Manuscript: Proceedings of a Seminar, ed. M. E. D’Imperio (1976); transcription online | the two statistical dialects, A and B, which change with the handwriting |
| G. Hodgins, Accelerator mass spectrometry radiocarbon determination of the Voynich manuscript parchment, University of Arizona AMS Laboratory (announced 2009); results summarized at voynich.nu/extra/carbon.html | the radiocarbon date of the vellum, 1404–1438, from four samples; no peer-reviewed article exists |
| G. Rugg, An elegant hoax? A possible solution to the Voynich manuscript, Cryptologia 28 (2004) 31 | a Cardan grille slid over a table of word fragments mass-produces Voynich-like text |
| T. Timm, How the Voynich manuscript was created, arXiv:1407.6639 (2014) | the copy-and-modify proposal whose title the paper echoes |
| B. Hauer and G. Kondrak, Decoding anagrammed texts written in an unknown language and script, Trans. Assoc. Comput. Linguist. 4 (2016) 75 | the Hebrew proposal with fixed-rule anagramming within each word, which the paper tests |
| R. Clemens (ed.), The Voynich Manuscript, Yale University Press, New Haven (2016) | the authorized facsimile with essays on the book’s history and materials, cited for the study of its quires and binding |
| L. Fagin Davis, How many glyphs and how many scribes? Digital paleography and the Voynich manuscript, Manuscript Studies 5 (2020) 164 | the five scribal hands, an attribution the paper adopts without testing |
| T. Timm, One hand, five labels: A critical examination of the five-scribe hypothesis for the Voynich manuscript, Zenodo preprint, doi:10.5281/zenodo.19169450 (2026) | the objection that a single scribe wrote the book in a hand that drifted |
| T. Timm and A. Schinner, A possible generating algorithm of the Voynich manuscript, Cryptologia 44 (2020) 1 | the “self-citation” generator; on withheld pages its local copying is a minor component |
| C. L. Bowern and L. Lindemann, The linguistics of the Voynich manuscript, Annu. Rev. Linguist. 7 (2021) 285 | the review judging the text most likely a natural language in a non-standard encoding |
| M. A. Greshko, The Naibbe cipher: A substitution cipher that encrypts Latin and Italian as Voynich manuscript-like ciphertext, Cryptologia (2025) 1 | the Naibbe cipher, executable by hand, tested here from its published tables |
| R. Zandbergen, The Voynich manuscript, www.voynich.nu (accessed 28 July 2026) | the volunteer-maintained site of the Zandbergen–Landini transliteration on which all counts are taken, also cited for the book’s early history |
| Beinecke Rare Book and Manuscript Library, The Beinecke Cipher (Voynich) Manuscript, MS 408, Yale University Library | the library’s page for the book, linking to the high-resolution digital facsimile from which the folio images on this page come (public domain) |